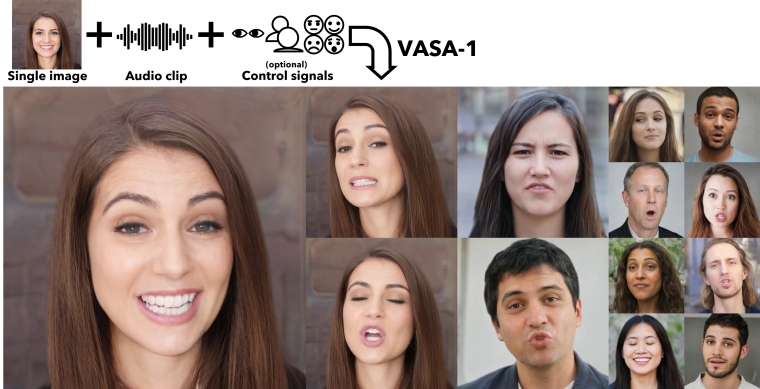
Microsoft Research Asia scientists have come up with a way to generate "lifelike audio-driven talking faces" in real time, using just a single portrait photo and adding an audio track with speech for them.
Called VASA-1, the first iteration of the "visual affective skills" framework can produce very lifelike avatars - some would call them deepfakes - that emulate human conversational behaviours.
The researchers are able to generate 512 by 512 pixel videos at up to 40 frames per second, and a low, 170 millisecond startup latency.
Images can be likenesses of humans, or artificial intelligence generated portraits... or paintings, like Leonardo da Vinci's Mona Lisa:
This is diffusion AI model technology, that works by removing noise to generate the images. The researchers have made it possible to add controls to the talking heads, so as to give them human-like emotional behaviours, different poses, angles, and expressions.
Songs and other languages than English can also be used for VASA-1.
While the VASA-1 talking heads are not yet good enough to be easily mistaken for real people, the researchers are still concerned about the possibility that they could be abused.
Our research focuses on generating visual affective skills for virtual AI avatars, aiming for positive applications. It is not intended to create content that is used to mislead or deceive. However, like other related content generation techniques, it could still potentially be misused for impersonating humans. We are opposed to any behaviour to create misleading or harmful contents of real persons, and are interested in applying our technique for advancing forgery detection. Currently, the videos generated by this method still contain identifiable artifacts, and the numerical analysis shows that there's still a gap to achieve the authenticity of real videos.
While acknowledging the possibility of misuse, it's imperative to recognise the substantial positive potential of our technique. The benefits – such as enhancing educational equity, improving accessibility for individuals with communication challenges, offering companionship or therapeutic support to those in need, among many others – underscore the importance of our research and other related explorations. We are dedicated to developing AI responsibly, with the goal of advancing human well-being.
Due to the risk of abuse, the researchers say there won't be an online demo released, or an application programming interface, nor a product or similar implementation. Not until they are certain that the technology will be used responsibly, "and in accordance with proper regulations", that is.
Elsewhere, services that are able to clone voices quickly have already been released, such as Eleven Labs that handles multiple languages and accents.
We welcome your comments below. If you are not already registered, please register to comment
Remember we welcome robust, respectful and insightful debate. We don't welcome abusive or defamatory comments and will de-register those repeatedly making such comments. Our current comment policy is here.